a small model for structured extraction.
OpenSML-JSONLite-175M-Instruct is a research candidate for source-grounded extraction. The model and source repositories currently require access; public release readiness and a weight license have not been established.
OpenSML-JSONLite-175M-Instruct produces the entire JSON object in a single autoregressive request. The current checkpoint is SFT-100, update 469. It continues OpenSML-Base-175M through grounded QA, requested-field extraction, focused extraction and directly supervised native JSON training.
The runner retains the model’s raw output and validates it afterward. There is no constrained decoder, fieldwise JSON assembler or output repair. Valid JSON does not establish that the extracted values are correct.
The supported contract is a flat, closed object with 1–8 required fields: strings, nullable strings or arrays of strings. Missing arrays target []; missing nullable strings target null. Case, spelling and source order are preserved. The verified training scope primarily covers seven SNIPS domains and 39 field definitions.
see the actual model output.
These are recorded native generations from the packaging verification, not a live inference demo. References were compared after generation and were never included in the model input.
Source text
Play the track Blue Lantern by Mira Sol.
Supplied JSON Schema
{
  "type": "object",
  "properties": {
    "track": {
      "type": "array",
      "items": {
        "type": "string"
      },
      "description": "track name"
    },
    "artist": {
      "type": "array",
      "items": {
        "type": "string"
      },
      "description": "performer or musical artist"
    },
    "album": {
      "type": "array",
      "items": {
        "type": "string"
      },
      "description": "album name"
    }
  },
  "required": [
    "track",
    "artist",
    "album"
  ],
  "additionalProperties": false
}
Raw model output
{"album":[],"artist":["Mira Sol"],"track":["Blue Lantern"]}FIELD-29 · exact reference match
structure and correctness, measured separately.
The adapted SNIPS held-out panel has 1,444 requests. Entire-request correctness requires natural completion, strict JSON and schema validity, and exact agreement with every reference value.
| Measure | Result |
|---|---|
| Entire request correct | 1,191 / 1,444 · 82.48% |
| Field accuracy | 3,193 / 3,497 · 91.31% |
| Extracted-value precision / recall / F1 | 90.55% / 90.41% / 90.48% |
| Missing-field accuracy | 92.46% |
| Schema-valid JSON | 1,441 / 1,444 · 99.79% |
| False abstentions / unsupported values | 111 / 30 |
| Token-limited outputs | 0 |
Canonical string-array schemas score 1,156/1,388 (83.29%). Renamed-key and nullable-string stress views score 19/28 and 16/28. The extra views reuse held-out sources.
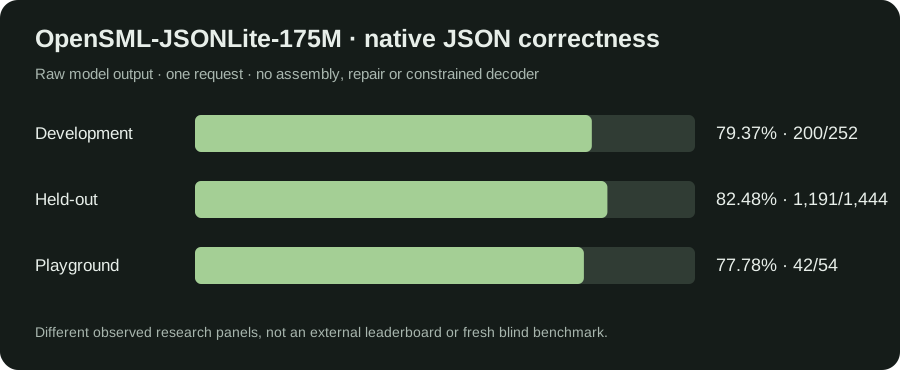
Complete-request correctness by domain
| Domain | Correct / requests | Rate |
|---|---|---|
| AddToPlaylist | 168/206 | 81.55% |
| BookRestaurant | 156/208 | 75.00% |
| GetWeather | 168/206 | 81.55% |
| PlayMusic | 149/208 | 71.63% |
| RateBook | 188/204 | 92.16% |
| SearchCreativeWork | 197/208 | 94.71% |
| SearchScreeningEvent | 165/204 | 80.88% |
The separate 54-case local diagnostic scores 42/54 (77.78%); its 12 previously authored natural examples score 7/12. These observed research panels have prior exposure and are not a fresh blind benchmark or external leaderboard.
native MLX, a custom architecture.
- Parameters
- 175,611,648
- Layers / hidden / FFN width
- 24 / 768 / 2,048
- Query / key-value heads
- 12 / 4 · grouped-query attention
- Normalization / MLP
- RMSNorm + Q/K norm / SwiGLU
- Positions
- RoPE · base 10,000
- Tokenizer
- Frozen 32,000-token byte BPE
- Embeddings
- Tied input/output · no linear biases
- Weights
- 351,242,342 bytes · BF16
The verified runtime is Apple Silicon macOS, Python 3.11 and stock MLX 0.32.3. Use the supplied native runner; this is not a Transformers AutoModel or MLX-LM auto-loader export.
from a pretrained base to native JSON.
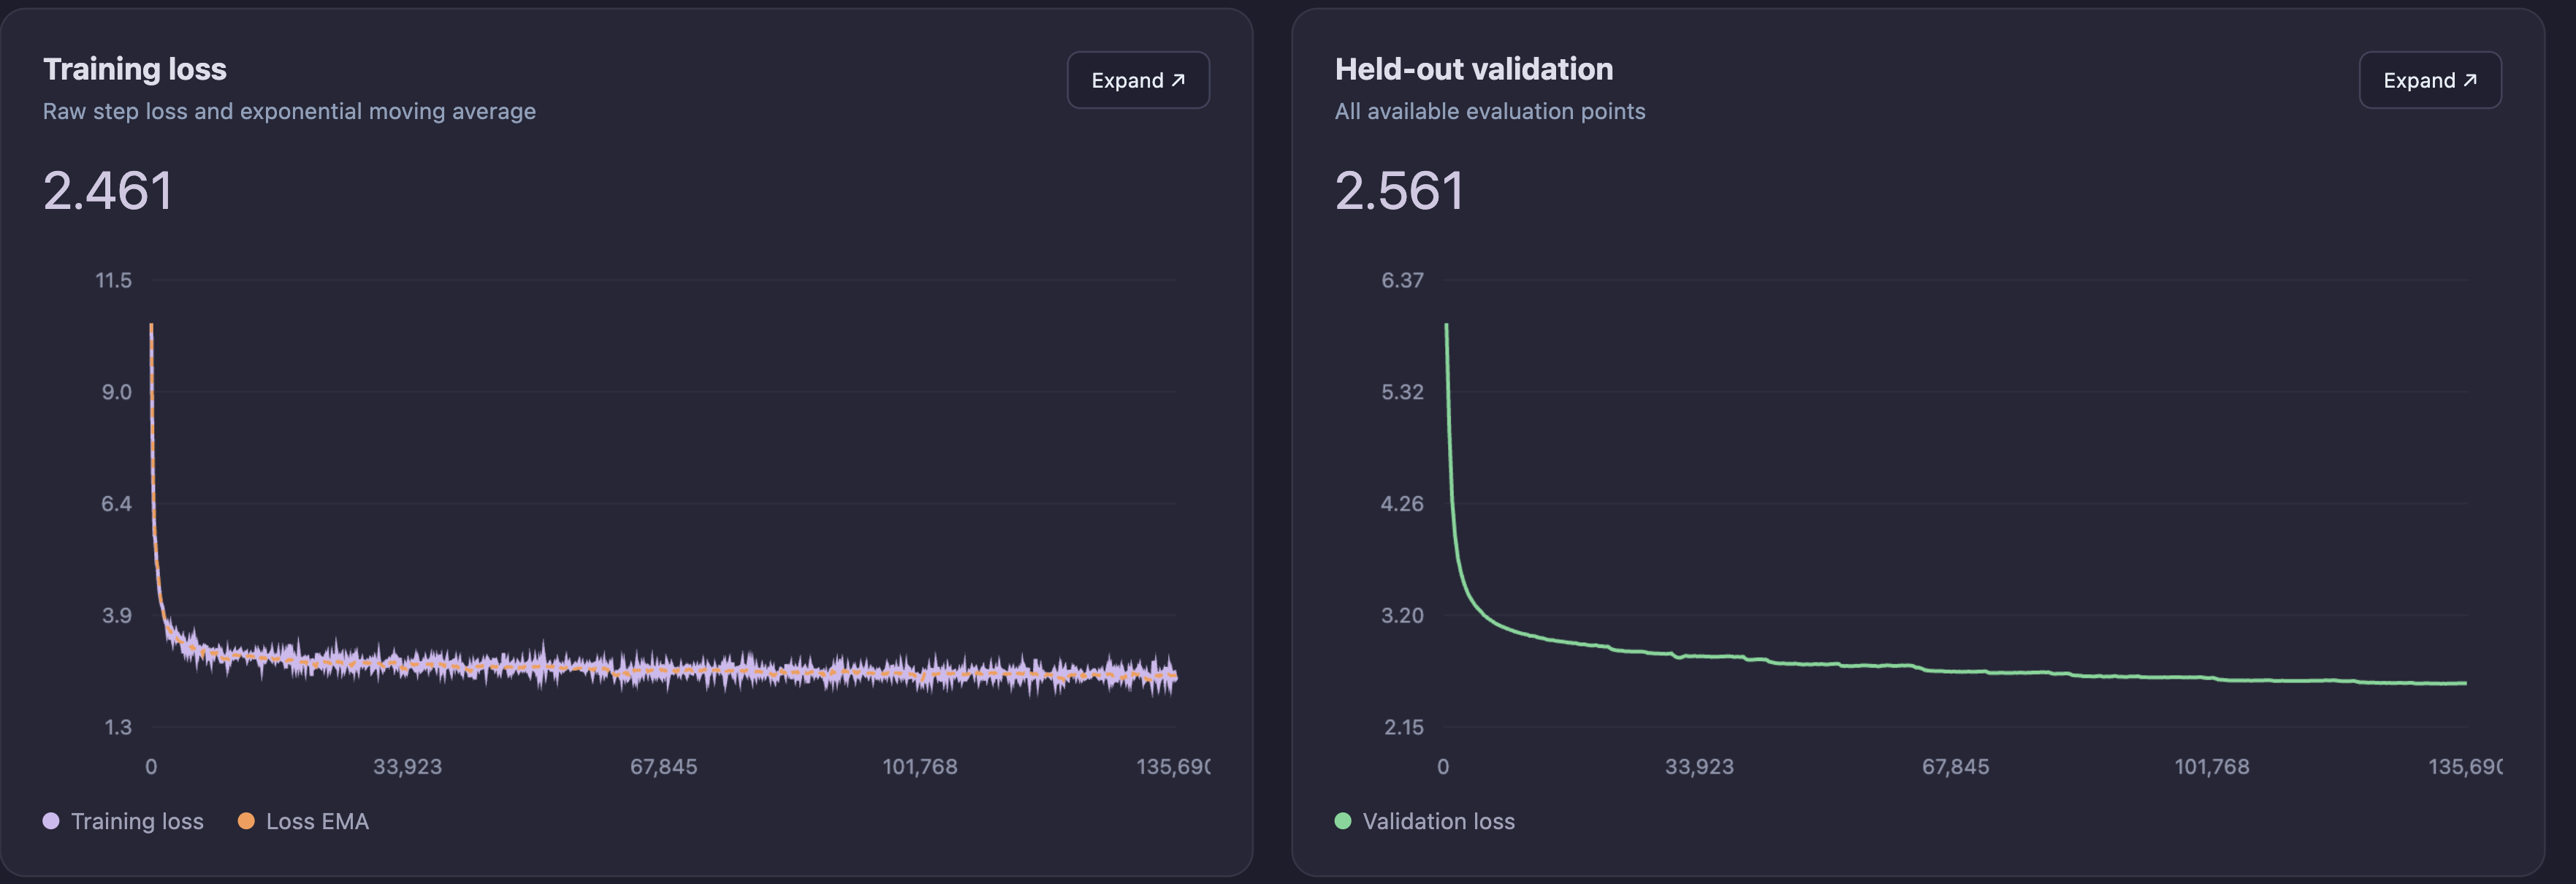
The 175.6M base was trained from random initialization on 17,300,111,360 lifetime token positions using the five-Mac Thunderbolt/RDMA cluster. These are processed positions, not unique corpus tokens. The 150M model did not initialize these weights; its frozen tokenizer was reused.
The intended pretraining mixture was FineWeb-Edu (50%), DCLM-Edu (18%), English FineWiki (13%), Cosmopedia v2 (9%) and educational Python (10%). Selected-base validation loss was 2.5563.
| Stage | Selected update | Presentations |
|---|---|---|
| Grounded QA · SFT-065 | 469 | 15,008 |
| Requested-field extraction · SFT-068 | 379 | 12,115 |
| Focused extraction · SFT-093 | 160 | 5,120 |
| Native JSON · SFT-100 | 469 | 15,000 |
The final stage uses 12,115 distinct training sources, with additional renamed-key and nullable-string views. It performs one full-weight pass with batch 32, microbatch 2, fresh AdamW and a 5e-6 to 1e-6 schedule. Only assistant JSON and stop tokens contribute to the loss. Development selection was frozen before the 1,444-request test.
run it locally, with repository access.
The Hugging Face package contains weights, tokenizer, configuration, a root runner and native source archive. Authenticate with an account that has access before downloading.
python3 -m venv .venv
source .venv/bin/activate
python -m pip install huggingface_hub
hf auth login
hf download wzebrowski/OpenSML-JSONLite-175M --local-dir OpenSML-JSONLite-175M
cd OpenSML-JSONLite-175M
python -m pip install -r requirements.txt
python inference.py --example 29
python inference.py --text-file request.txt --schema-file schema.json
Default stdout is unmodified model text. --json adds parsed values, structural validation, stop metadata and example correctness. Input text, full schema, fixed instructions and output budget share 2,048 tokens; overlong inputs are rejected without truncation. Default decoding is greedy with at most 256 output tokens.
The runner verifies the weight and source-archive identities. Clean-runtime verification matches raw text and stop reasons on all 54 recorded examples; it is packaging parity, not an independent accuracy test. Generation runs offline after download and dependency installation.
where it still falls short.
Observed failures include unsupported cities, omitted second values, merged names, incomplete spans, confused entity types, duplicate keys and malformed nullable-string output. Schema validity checks structure; it cannot certify factual accuracy.
Unfamiliar domains, long documents, corrections and complex associations need further validation. Nested objects, numeric/boolean outputs, enums, references and advanced schema constraints are outside the verified runner contract. General dialogue, coding, multilingual quality, confidence calibration and prompt-injection robustness are not established.
The repository’s Apache-2.0 source license does not assign a model-weight license. Weight licensing is not yet assigned; data and dependencies retain their own terms.
inspect the evidence.
Records dated October 14, 2026. Selected weight SHA-256:
656f45015aab548465d93bed0b57e687497163741885da7364872851fa17e9a4