a vocabulary of its own.
Custom tokenizers and carefully prepared training data lay the groundwork for learning.
Custom tokenizers and carefully prepared training data lay the groundwork for learning.
We train models from scratch on Apple Silicon, exploring what accessible hardware can make possible.
We share evaluations, training records and limitations so others can inspect the results and build on the work.
Our current cluster brings five Apple Silicon Macs together over a Thunderbolt RDMA ring. Explore the hardware, how the workload is split, and how every worker stays in sync.
Inside distributed trainingSee how our models learned.
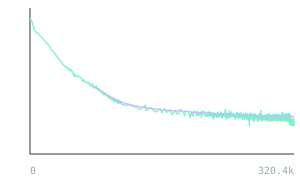
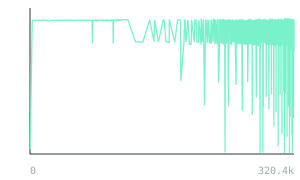
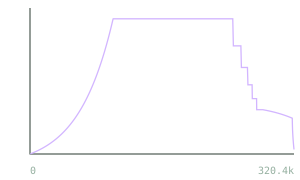
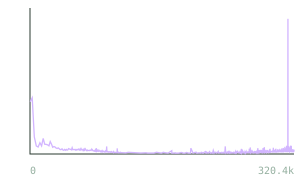
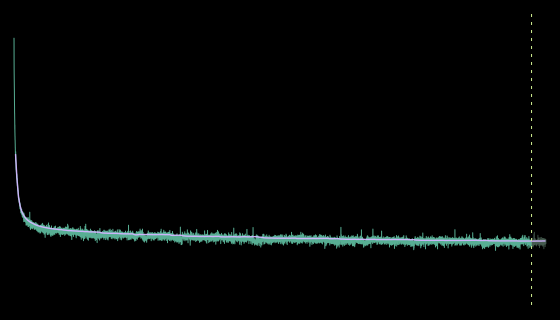
Follow Solstice-1-175M through 42B pretraining tokens and three fine-tuning stages. Replay the curves and inspect the inherited checkpoints.
Explore the observatory