 OpenSML
Making training faster without making the model smaller
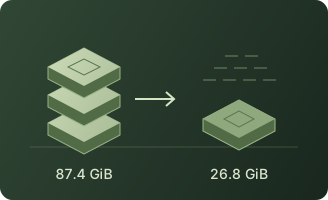
Sequential accumulation reduced peak active memory from 87.4 to 26.8 GiB on one worker. Workload and cache tuning then delivered roughly 27% more throughput in short pilots.
Sequential accumulation reduced peak active memory from 87.4 to 26.8 GiB on one worker. Workload and cache tuning then delivered roughly 27% more throughput in short pilots.
How parallel computation, workload balance and gradient synchronization bring many workers into one training process.
The first release, documented: architecture, data, pretraining, instruction tuning, evaluations and limitations.
Short notes will appear here as they’re published.
From a quick observation to a closer look.
Research shared as the work unfolds.